Try Deep Extract for Free
New customers can get up to $1,000 in free credits to try Deep Extract on your hardest extraction use cases.
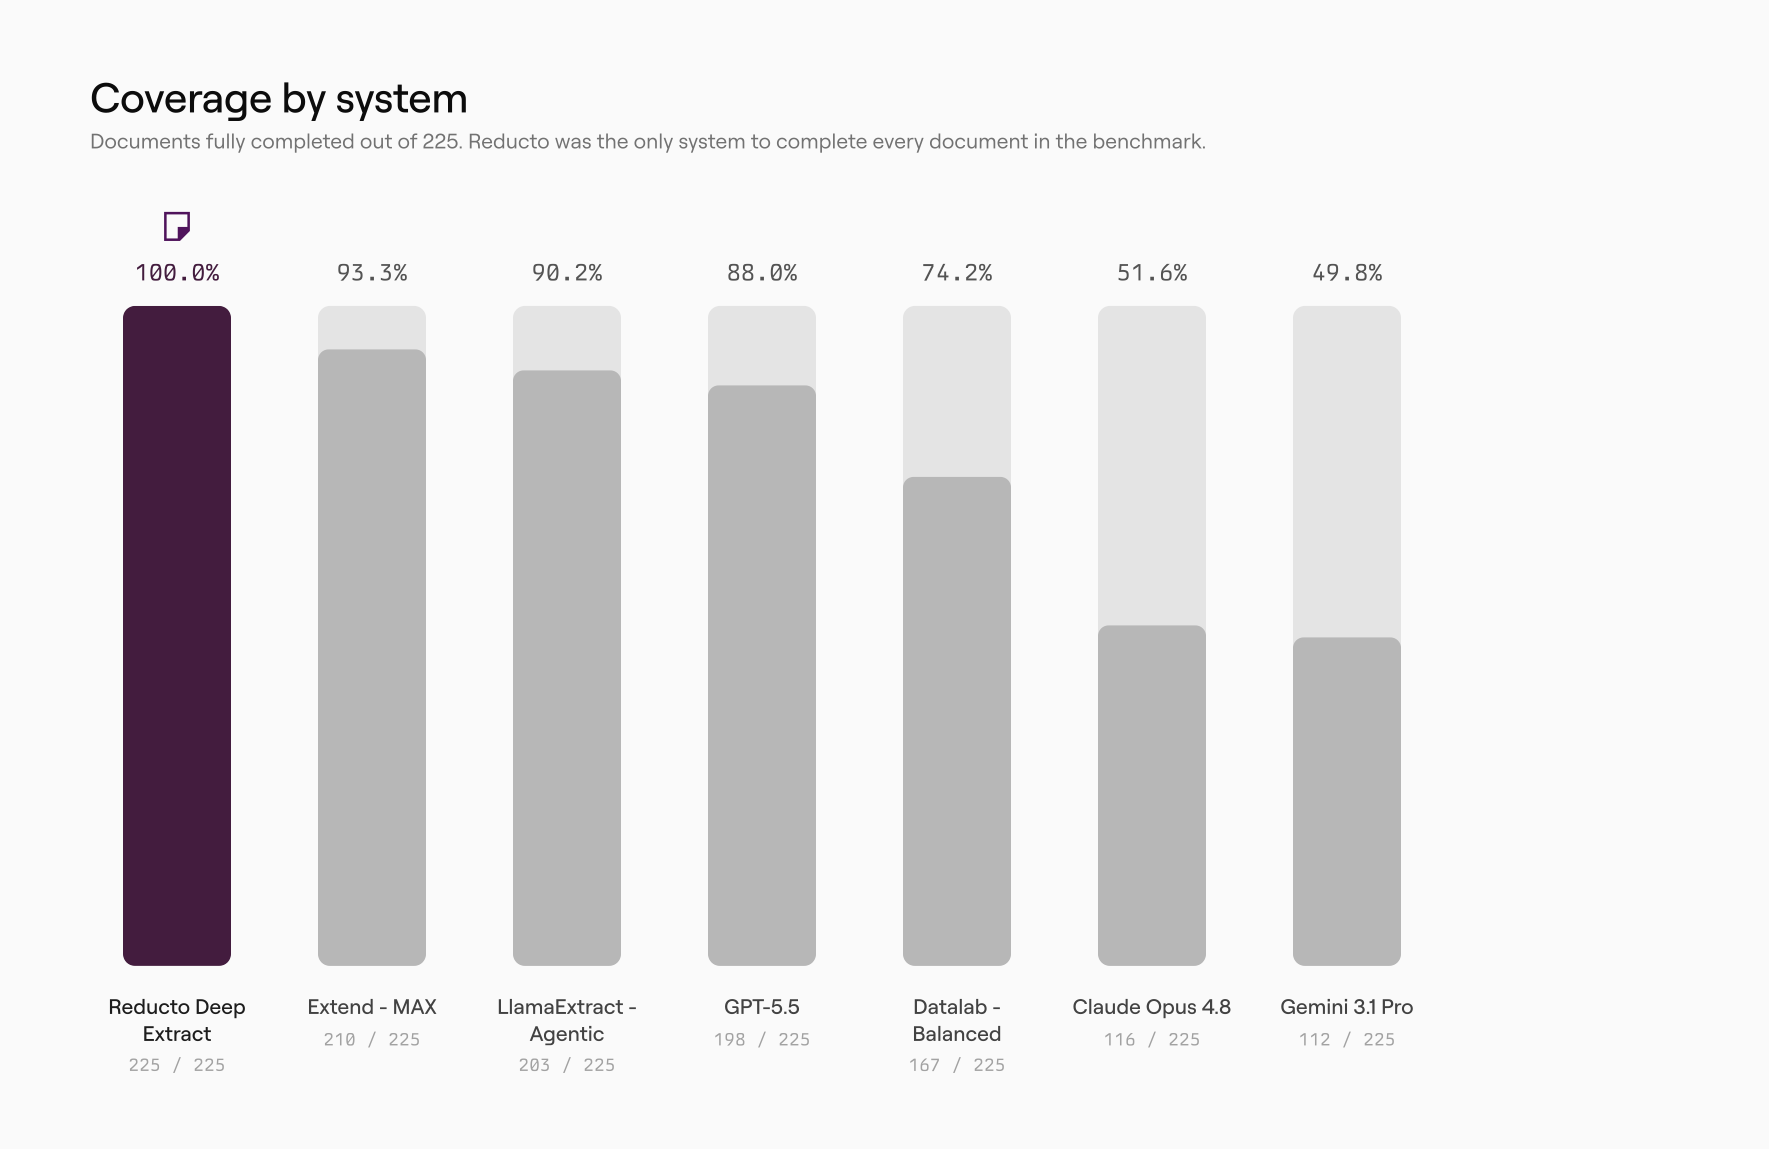
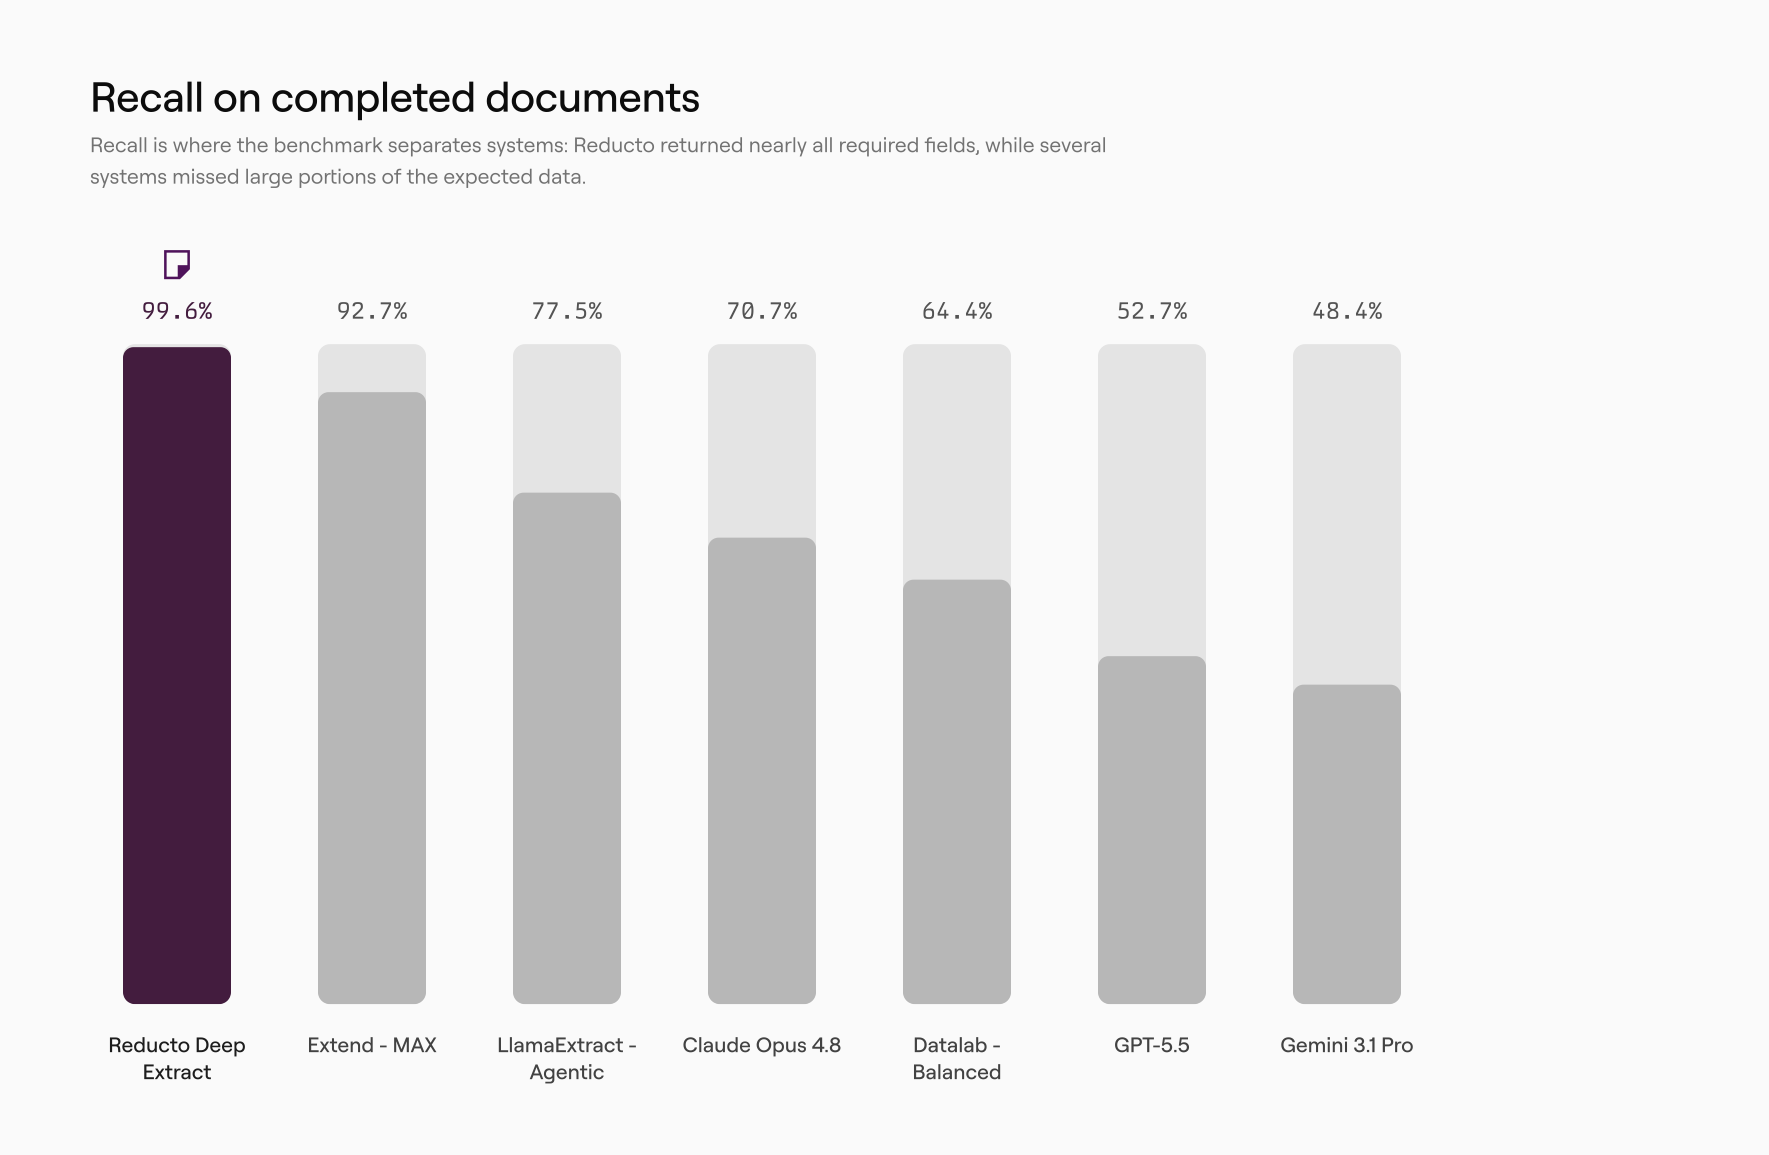
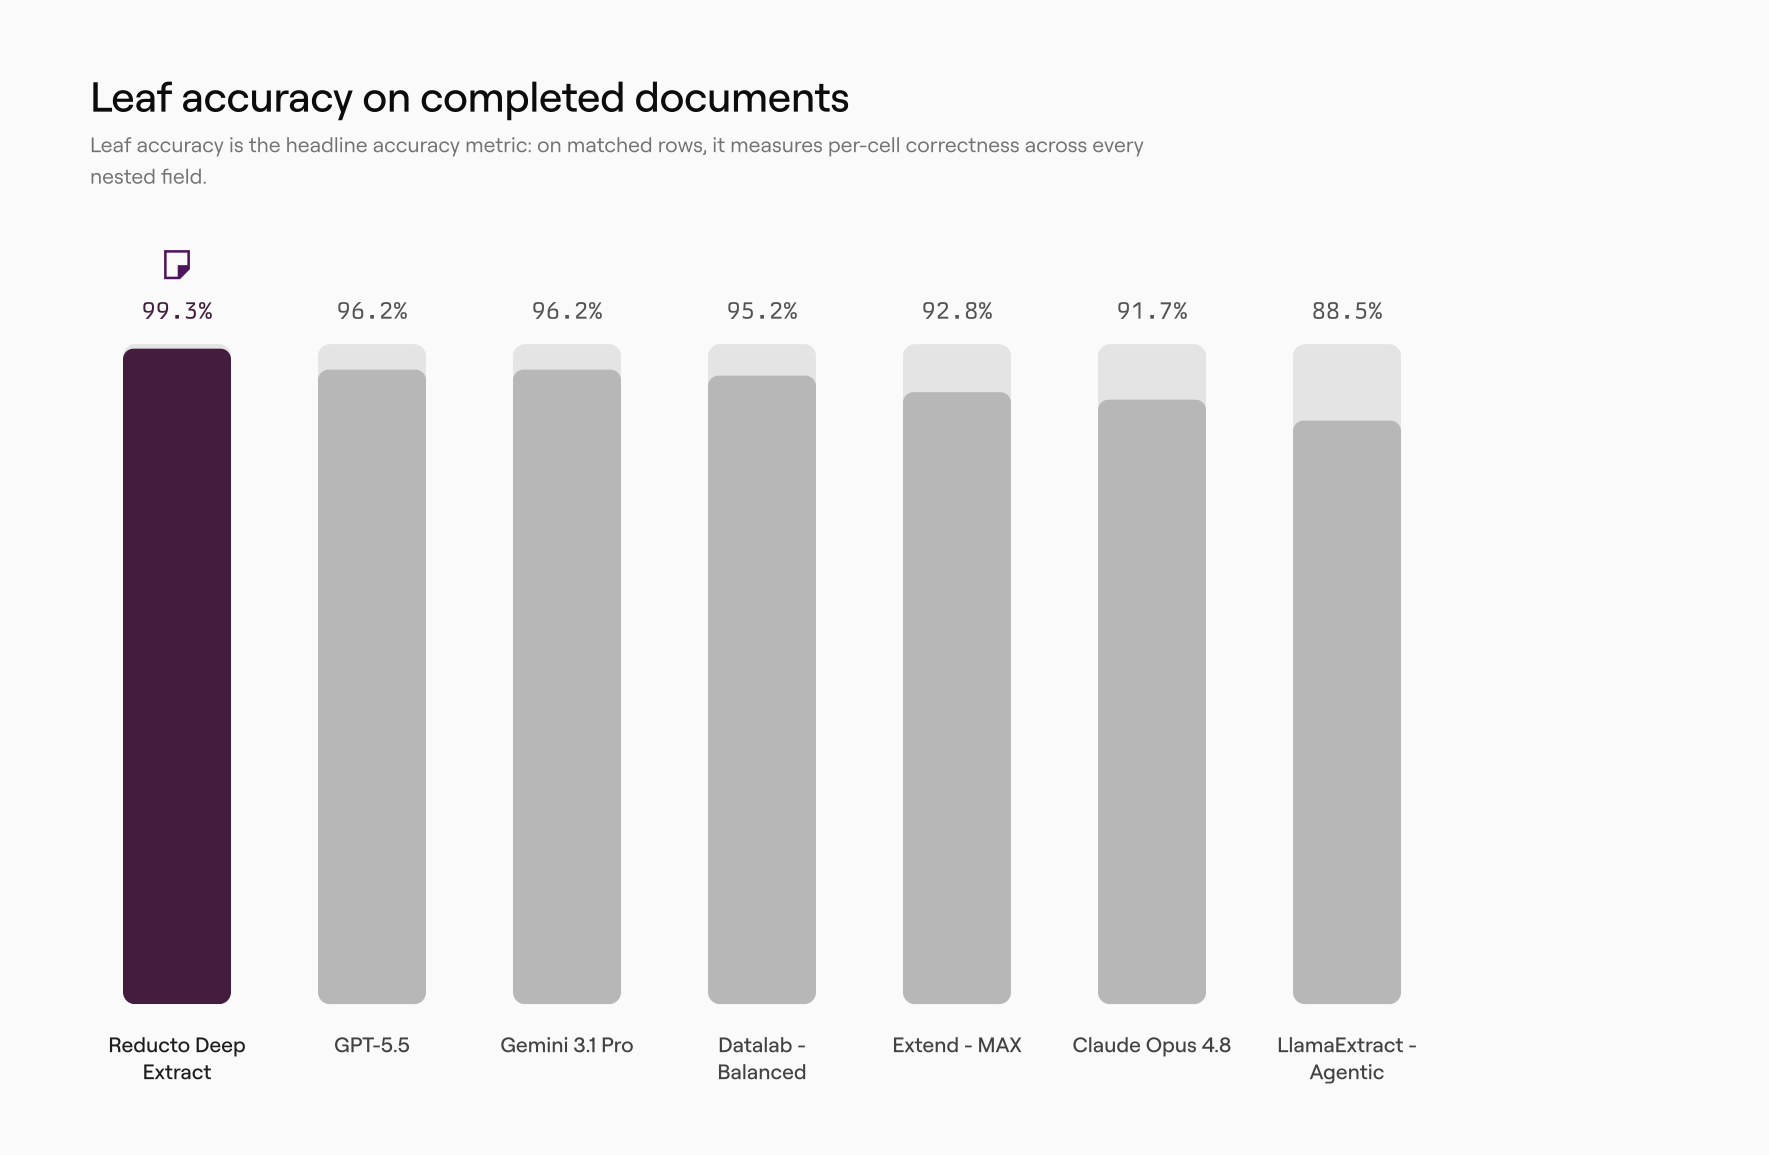
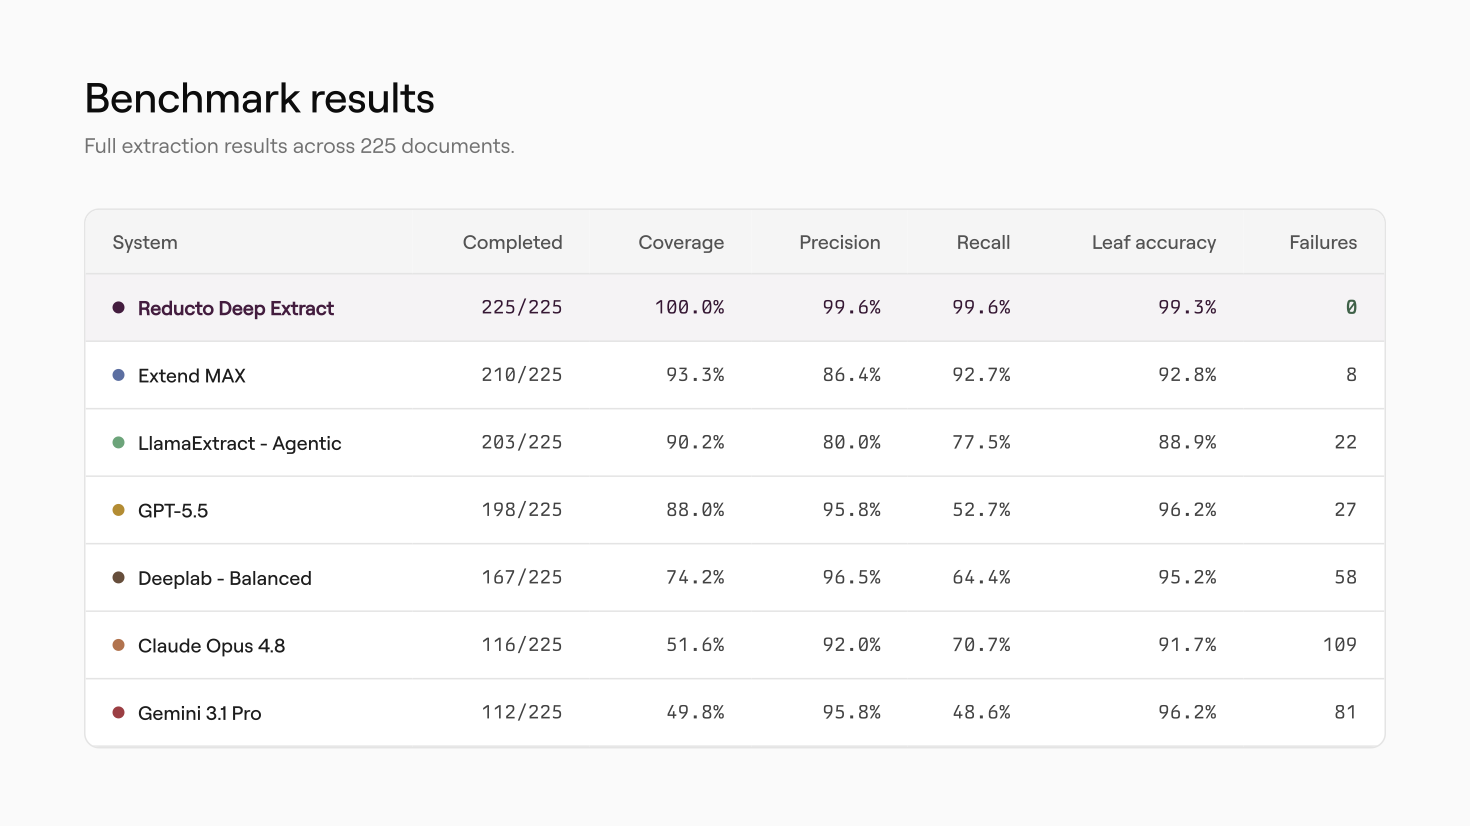
Deep Extract ranked first overall in micro1's independent document extraction benchmark — 100% completion and 99.6% precision and recall across 225 real-world documents. Full results below.
Trusted by companies worldwide



"With Reducto, we tripled our processing speed and built a pipeline that accurately processes millions of documents per month, all while reducing engineering time spent on chunking by 90%."
— Co-founder, Legora

What is Deep Extract?
Deep Extract is the highest-accuracy extraction mode on Reducto's agentic document platform. Where single-pass extraction reads a document once and hopes for the best, Deep Extract plans, extracts, and verifies its own output across the full document — built for invoices, financial statements, and claims where every field matters.
Agentic verification
Instead of a single pass, Deep Extract runs an agentic loop that re-reads the document and verifies its own output, so hundreds of line items come back complete — no truncated arrays, no skipped pages.
Citations on every value
Every field is returned as typed JSON with a citation and bounding box back to the exact page it came from, so every value in your pipeline is auditable.
No templates or retraining
Define a schema and go. Deep Extract handles complex tables, scans, handwriting, and 30+ file types out of the box — no per-document templates to maintain.
Independently benchmarked, first overall
We commissioned micro1, an independent data lab, to build and publish the first benchmark for complex structured extraction: 225 real documents — invoices, financial statements, and claims, averaging 88,700+ fields each — with a human-validated answer key. micro1 sourced every document and published the results. Six systems were tested: Reducto Deep Extract, Extend MAX, LlamaExtract-Agentic, GPT-5.5, Claude Opus 4.8, and Gemini 3.1 Pro.
100%
Coverage
225 of 225 documents completed
99.6%
Precision
Returned values that match ground truth
99.6%
Recall
Required fields actually found
99.3%
Leaf accuracy
Individual cell values correct
What the benchmark measures
Coverage
Whether a system can complete a full extraction for every document, or fails and returns nothing.
Precision
The fraction of what a system returned that is actually real and exists in the ground truth.
Recall
The fraction of what should have been returned that the system actually found.
Leaf accuracy
The fraction of individual cell values that match the answer key on the rows a system got right.
See the same results on your documents
Get up to $1,000 in free credits and run Deep Extract on your hardest extraction use cases.